
Marketing data aggregation is the process of collecting data from ad platforms, analytics tools, and CRMs, then standardizing and summarizing it into one dataset you can trust. Done right, it gives you a single source for cross-channel KPIs and clean, model-ready inputs for reporting and marketing mix modeling. The rest of this guide walks through how that pipeline works and how to build one that holds up.
TL;DR:
- Choose weekly or monthly rollups when privacy noise accumulates across small summaries; use daily data only when faster issue detection outweighs added volatility.
- Before building dashboards, define a canonical schema, version campaign mappings, trace each field to its source, and assign one owner to approve changes.
- Aggregate models can confuse nonlinear response with changing effectiveness, so test material budget decisions using geo holdouts, synthetic controls, or deliberate market level spend shifts.
- A single connector can reduce integration and authentication upkeep, but verify that every needed platform has an actively maintained connection before relying on coverage.
Table of Contents
- How marketing data aggregation works: pipeline and levels
- Benefits and use cases once your data is aggregated
- Privacy, noise, and measurement constraints in practice
- Practical checklist for choosing or building an aggregation solution
- Modeling considerations: MMM identification and when to test
- How a single-connector pattern speeds up aggregation
- Where marketing data aggregation is headed
- Get automated marketing reports without building the pipeline yourself
- FAQ
- Sources
How marketing data aggregation works: pipeline and levels
Every aggregation system, whether you build it internally or buy one, moves through the same four stages. Skipping or rushing any of them is usually why “aggregated” dashboards still disagree with each other.
- Ingestion: pulling raw data from APIs, exports, or tags into a staging area before anything is cleaned.
- Transformation (ETL): mapping fields to a common schema, deduplicating records, and resolving naming mismatches across platforms.
- Canonical storage: holding the cleaned data in a warehouse or data mart with consistent field names and types.
- Presentation and export: surfacing the data through dashboards, flat files, or API feeds for whoever needs it next.
Once the pipeline exists, you also have to decide what level you’re aggregating at. Marketers typically work across three levels: micro (individual transactions or events), meso (campaign or channel-level rollups), and macro (brand or portfolio-level summaries used for executive reporting). Layered on top of that are the dimensions you aggregate by, mainly time (daily, weekly, monthly), geography (market, region, store), and category (product line, audience segment, channel).
The real trade-off sits between granularity and usability. Finer granularity gives you more precision but also more noise and more chances for mismatched definitions between platforms. Coarser rollups are easier to trust and faster to compute, but they can hide the signal you actually need for a decision, like which creative within a campaign is underperforming. Cadence interacts with this directly: a weekly rollup smooths out day-to-day volatility from tracking gaps or ad-platform modeling quirks, while a daily feed gives you faster detection of problems at the cost of more noise per data point. The IAB’s guidance on modernizing marketing mix models recommends centralizing cleaned inputs in a warehouse with a tidy, documented schema specifically because inconsistent granularity between sources is one of the most common reasons aggregated datasets fail to support reliable modeling.
Benefits and use cases once your data is aggregated
The payoff from aggregation shows up fastest in reporting, but it extends well past the dashboard.
- Standardized cross-channel dashboards: stakeholders see one set of KPI definitions instead of reconciling exports from five tools.
- Cleaner MMM inputs: marketing mix models depend on consistent, tidy aggregate data, and the IAB’s companion guide ties model reliability directly to input cleanliness and provenance.
- Portfolio-level benchmarking: comparing channel or campaign performance against your own historical baseline, not just platform-reported numbers.
- Audience segmentation and funnel analysis: combining CRM and behavioral data to see where prospects stall, not just where they convert.
- Anomaly detection: a unified dataset makes it easier to spot a sudden spend or conversion shift that would be buried in a single platform’s view.
marketers plan to invest in marketing mix modeling within the year, and 27.6% already consider it their most reliable measurement method](https://www.emarketer.com/content/mmm-reports-statistics-marketing-trends). That shift only works if the underlying data is aggregated consistently enough to feed a model in the first place. A third-party analysis of analytics-driven marketing makes a similar point: teams that centralize and act on their data outperform those still working from siloed platform reports. Automated reporting built on top of this foundation also cuts the manual work of stitching together weekly updates, which is often where analyst time disappears.
Privacy, noise, and measurement constraints in practice
Privacy-preserving measurement has changed what “aggregation” means at the data-collection layer, and it’s worth understanding before you design a pipeline around it. Systems like the Privacy Sandbox process attribution data through an aggregation service that batches, decrypts, and adds statistical noise before returning summary reports, rather than exposing individual-level events.

That noise isn’t a bug you can filter out. Per Privacy Sandbox guidance on working with noise, summing multiple summary values also sums the noise attached to each one, so a dashboard built from many small, frequent rollups can end up noisier than one built from fewer, larger rollups. The practical fixes are straightforward: use coarser aggregation keys instead of highly granular ones, request longer rollup windows rather than hourly ones, apply scaling factors to recover signal, and split your privacy budget deliberately across the queries that matter most rather than spreading it thin.
marketers plan to invest in MMM this year](https://www.emarketer.com/content/mmm-reports-statistics-marketing-trends), a methodology that depends on aggregate inputs and is directly affected by how much noise those inputs carry.
Deduplication and filtering before data enters your warehouse also matter more under noisy aggregation, since any duplicate record gets amplified rather than averaged out. None of this makes aggregation unreliable, but it does mean the keys and cadence you choose upstream directly determine what your downstream models can actually estimate.
Pro Tip: When in doubt, choose a longer reporting window over a more granular one. Noise shrinks relative to signal as you widen the rollup.
Practical checklist for choosing or building an aggregation solution
Whether you’re evaluating a vendor or designing an internal stack, the same checks separate a system that holds up from one that quietly drifts out of sync.
- Confirm connector coverage and maintenance. Verify that every platform you rely on has an actively maintained connector, since a stale API integration is often how discrepancies start.
- Define a canonical schema before building anything. Agree on field names, units, and campaign-naming conventions across teams first, not after the data starts flowing.
- Establish data provenance and a source register. Every field should be traceable back to the system and query that produced it.
- Set update cadence and latency expectations. Decide which KPIs need daily refreshes and which can run weekly without losing value.
- Document retention policies and cost model. Know how long raw and aggregated data are kept and what each additional connector or query costs.
- Assign a named data steward. One person or team should own schema changes, not a rotating cast of whoever touched the pipeline last.
- Document every imputation and gap. When a channel is under-measured, the IAB’s guidance recommends pragmatic estimation over forcing noisy, granular attribution, as long as the estimate is documented.
- Version your mapping tables. UTM and campaign ID mappings change; keep a version history so historical reports stay reproducible.
- Align outputs with what analytics and finance actually need. A report that satisfies marketing but doesn’t reconcile with finance’s revenue numbers will get challenged eventually.
Our checklist for building omnichannel campaign analytics walks through several of these steps in more operational detail, including how to sequence them when you’re starting from scratch.
Pro Tip: Build the mapping table before you build the dashboard. A clean dashboard on top of a messy mapping table just hides the problem for a few weeks.
Modeling considerations: MMM identification and when to test
Marketing mix models run on aggregate inputs by design: weekly or monthly spend and outcome data, summarized across channels. That design choice is efficient, but it creates a specific risk. Research on MMM identification shows that nonlinear response curves and time-varying effectiveness can look statistically identical in standard aggregate data, meaning a model can fit the historical data well while assigning the wrong cause to the pattern it found.
The fix isn’t a better statistical trick applied after the fact. It’s experimentation. The same research recommends designing experiments that strategically manipulate spend, geo holdouts, synthetic control tests, or deliberate budget shifts in specific markets, to separate a genuinely nonlinear response from a channel that’s simply become more or less effective over time. Without that kind of intervention, two very different explanations can produce the same curve in your model output.
Granularity choices feed directly into this problem. The lookback window you choose determines how much history the model sees, and stock variables like AdStock (which model how an ad’s effect decays over time) are sensitive to the time grain you aggregate at. A model built on weekly data with a four-week AdStock decay will behave differently than the same model built on daily data with a 28-day decay, even if the underlying media plan is identical. The IAB’s guidance recommends triangulating MMM output with at least one other signal, an experiment or an attribution assist, before treating any single model’s read as the answer for a material budget decision. Our article on improving attribution modeling covers how broader data coverage helps triangulate these signals in practice.

How a single-connector pattern speeds up aggregation
A lot of the friction in marketing data aggregation isn’t the analysis, it’s the setup. Each new ad platform, analytics tool, or CRM typically means a new API integration, a new authentication flow, and a new set of field mappings to maintain. That overhead is why many teams delay building a proper pipeline for months.
A single-connector pattern changes that math. Instead of integrating each tool one by one, we connect through one interface to a broad set of intelligence tools and pull cross-referenced data without standing up separate integrations for each platform.
- One connection point instead of a growing list of individual API integrations to maintain.
- Cross-referenced reports that combine ad performance, SEO, and competitor data without manual reconciliation.
- Exportable outputs, including dashboards, PDFs, and other deliverable formats analysts and stakeholders can use directly.
Our post on automating ad performance analysis shows what this looks like in a single workflow, from pulling raw platform data to producing a report ready for a stakeholder meeting. For teams drowning in connector maintenance, this pattern shifts the work from pipeline upkeep to actually reading what the data says.
Where marketing data aggregation is headed
The next few years of marketing measurement will be shaped by two forces pulling in the same direction: privacy constraints pushing data toward cohorts and coarser aggregates, and AI tools that need clean, structured inputs to be useful at all. Those two trends reinforce each other more than most teams expect. A cohort-level dataset, built with consistent keys and documented provenance, is exactly the kind of input an AI layer can synthesize into a benchmark or a recommendation. A messy one just produces a confident-sounding wrong answer faster.
My honest read is that the teams who win this transition won’t be the ones with the flashiest AI dashboard. They’ll be the ones who did the boring work first: a canonical data store, a documented mapping table, a named owner for schema changes. Automation on top of a weak foundation just means bad numbers travel faster. Pair every automated workflow with a standing commitment to run experiments periodically, since even the best aggregate dataset still needs an occasional outside check to confirm the model reading it is right.
— Sergey
Get automated marketing reports without building the pipeline yourself
If the checklist above sounds like a lot of infrastructure to stand up before you see a single report, there are platforms designed to close that gap. Instead of integrating each ad platform, analytics tool, and competitor data source separately, some solutions connect agents to many intelligence tools through one connector, so you get cross-referenced reports without the setup work.
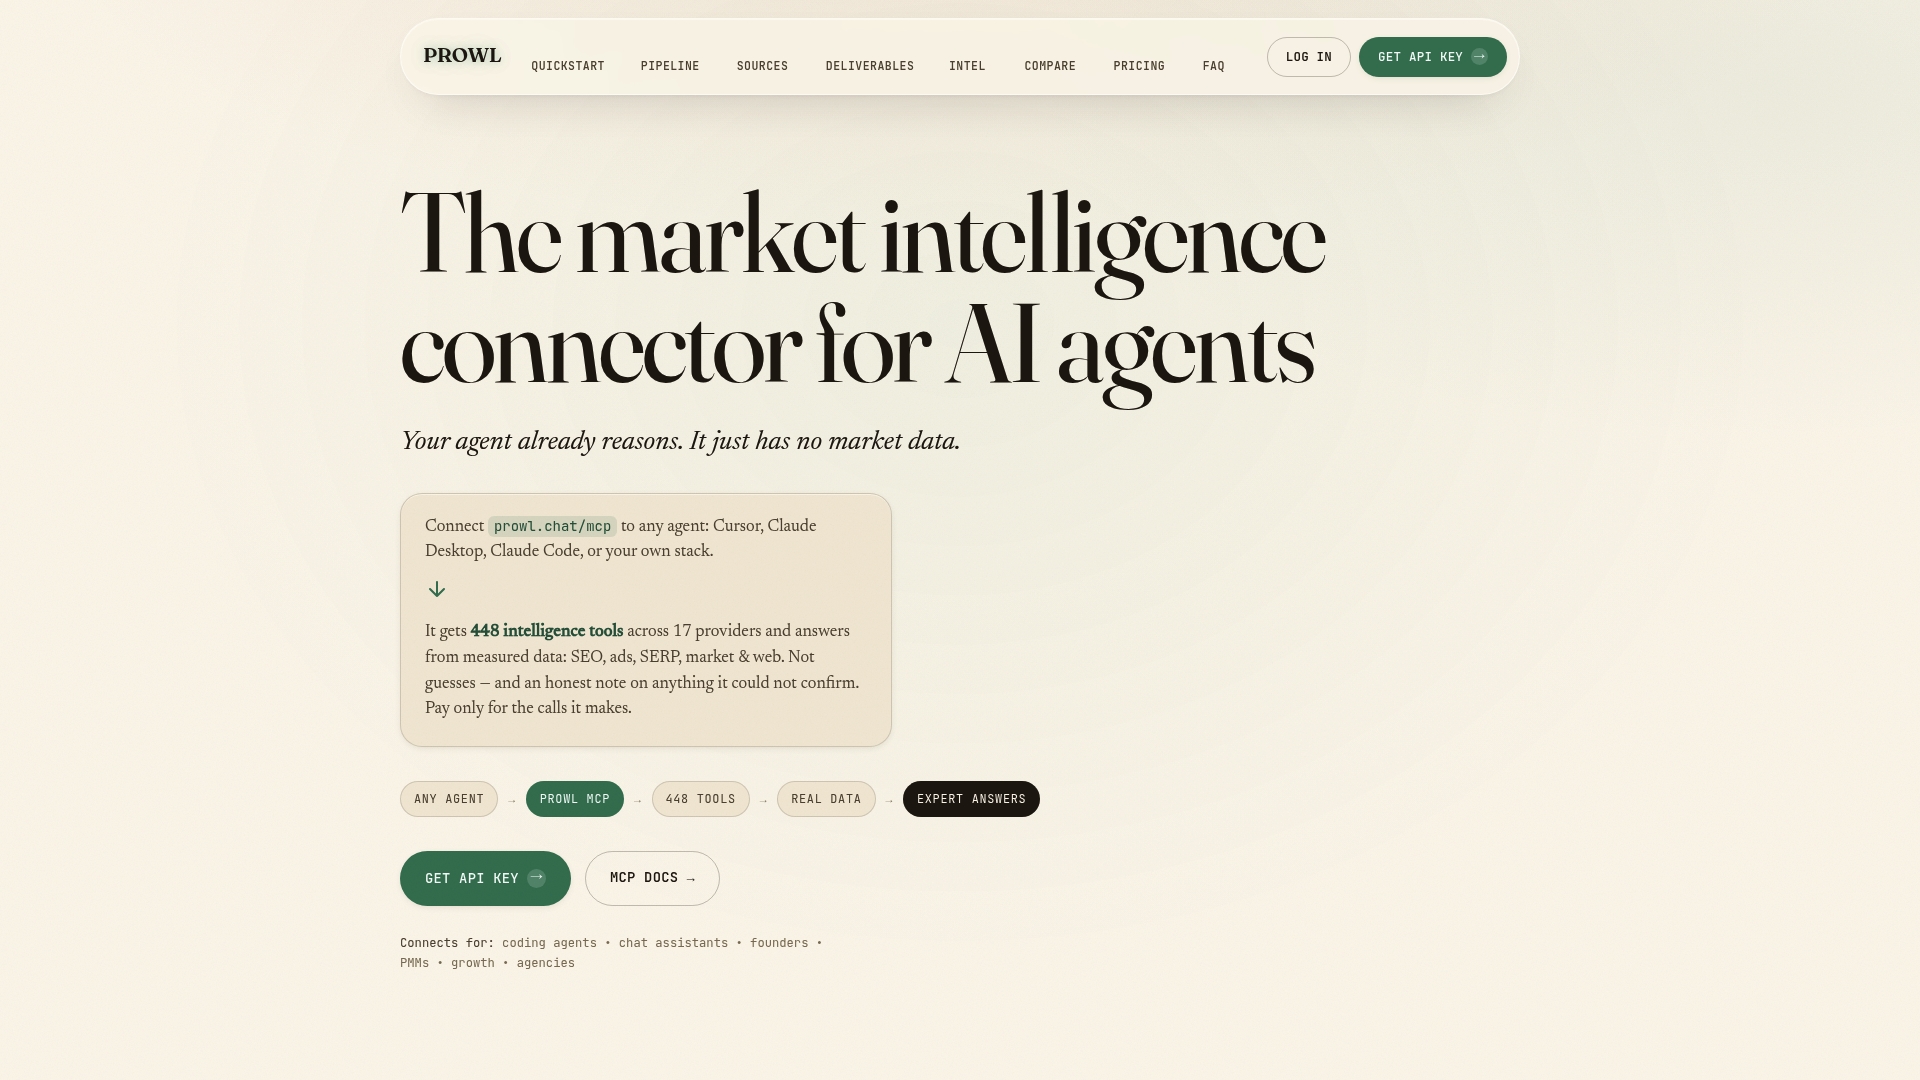
- One connector, broad coverage: ad performance, SEO, competitor analysis, and pricing research pull through a single integration instead of dozens.
- Automated reports: outputs are synthesized across sources rather than delivered as raw exports you have to reconcile yourself.
- Multiple deliverable formats: interactive reports, PDFs, infographics, and more, depending on what your stakeholders need.
This fits teams who need recurring competitive or performance reporting without hiring for pipeline maintenance, from agency analysts to in-house growth teams. See how it applies to your workflow on our use cases page, or check plans and credit options on our pricing page to get started.
FAQ
What is data aggregation?
Data aggregation is the process of collecting data from multiple sources and combining it into a summarized dataset, typically organized by time, category, or location. In marketing, this means pulling data from ad platforms, analytics tools, and CRMs into one consistent view instead of reviewing each source separately.
What are some examples of marketing data?
Common examples include ad platform metrics like impressions, clicks, and spend; site analytics like sessions and conversions; CRM data like orders and revenue; and email engagement metrics like opens and click-through rates. Each source typically uses its own naming conventions, which is why mapping them to a shared schema matters before aggregating.
What are the risks of using an aggregator?
The main risks are noise and inconsistency: privacy-preserving systems add statistical noise to summary data, and summing multiple noisy rollups compounds that noise. Poorly mapped schemas or undocumented imputations can also produce numbers that look clean but don’t reconcile with finance or platform-reported figures.
Should you enable data aggregation?
marketers plan to invest in MMM this year](https://www.emarketer.com/content/mmm-reports-statistics-marketing-trends). The key is pairing aggregation with a documented schema and periodic experiments, so the summarized numbers stay trustworthy as inputs to a decision.
Sources
- Privacy Sandbox — Aggregation Service: How it works
- IAB State of Data 2025 companion guide
- Your MMM is broken: Identification of nonlinear and time-varying effects in marketing mix models (arXiv)